Claude Fable 5.2 (Max) has achieved a score of 65 on the Artificial Analysis Intelligence Index, placing it well above the median score of 40 for models in its class. While this indicates a high level of intelligence, the model's performance comes with notable trade-offs in efficiency, requiring 45.0 minutes to complete a single Intelligence Index task compared to the median of 12.9 minutes for similar models.
Intelligence and Performance Metrics
The Claude Fable 5.2 (Max) model demonstrates high intelligence across a suite of evaluations including knowledge work, coding, science, and general knowledge. It achieved a score of 65 on the Artificial Analysis Intelligence Index, which incorporates nine distinct evaluations such as AA-Briefcase v1.1 and FrontierCode 2.0.
Despite its high intelligence score, the model's performance is hampered by significant latency. It recorded a time to first answer token of 171.16 seconds and an output speed of 101 tokens per second, contributing to a slow overall task completion time.
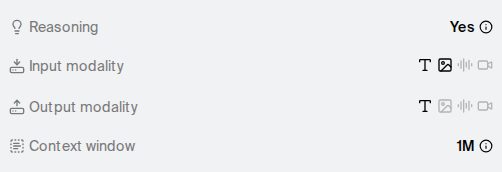
This screenshot provides the specific technical data points, such as token speeds and intelligence scores, mentioned in the performance metrics section.
“Claude Fable 5.2 (Max, Default Fallback) scores 65 on the Artificial Analysis Intelligence Index, placing it well above average among comparable models (median: 40).”
— Claude Fable 5.2 (max) - Intelligence, Performance & Price Analysis | Artificial Analysis
Cost and Verbosity Trade-offs
The model's operational costs are significantly higher than the industry average for its class. It costs $8.00 per 1M input tokens and $40.00 per 1M output tokens, resulting in an average cost of $26.54 per Intelligence Index task.
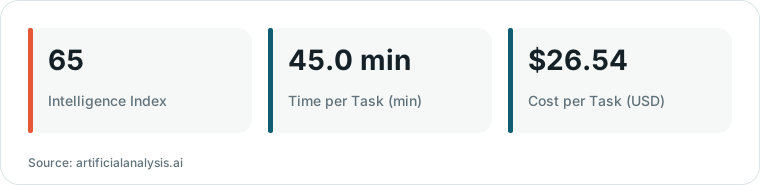
Chart drawn by HN Digest from figures reported by artificialanalysis.ai; values are shown as written in the source.
A primary driver of these costs is the model's extreme verbosity. During the Intelligence Index evaluation, it generated 275M output tokens, which is nearly four times the median of 72.8M tokens used by comparable models.
Model Variants and Limitations
The Claude Fable 5.2 release includes five different models tailored for different needs. For example, the 'Low' variant offers the best speed at 6.5 minutes per task and the lowest cost at $3.10 per task, illustrating a wide range of performance characteristics within the release.
While the Max variant provides the highest intelligence, the specific reasons for its high verbosity and slow completion times compared to its peers remain unaddressed in the current analysis. Furthermore, the specific names and metrics for the other three models in the release beyond the 'Low' variant are not currently detailed.
What Hacker News readers are saying
- Alternative: One commenter pointed out that the model's cost per task has doubled compared to its predecessor due to a significant increase in output tokens. comment ↗
- Skeptical: Another user suggested that the model's performance might be influenced by early access to benchmarks, noting it might not have finished running by the public release. comment ↗
- Experience: A commenter argued that the 'Max' version may be in a territory of diminishing returns and should only be used when every bit of performance is strictly necessary. comment ↗
Summarized opinions from the Hacker News thread, not verified facts. Read the full discussion ↗