A distilled Mamba model can achieve a perplexity of 14.01, nearly matching the 13.86 perplexity of a Pythia-1B Transformer teacher model. This finding, published by Apple Machine Learning Research, demonstrates a viable path for migrating the vast knowledge base of pretrained Transformers into State Space Models (SSMs), which offer superior efficiency during generation.
Bridging the Architecture Gap
State Space Models like Mamba have gained popularity as alternatives to Transformers because they offer reduced memory consumption and higher throughput during generation. However, the machine learning community has already invested heavily in training and refining Transformer architectures, creating a massive repository of pretrained knowledge.
A significant hurdle in adopting SSMs is that 'naïve' distillation—directly transferring knowledge from a Transformer to a Mamba model—often fails to preserve the teacher's performance. Previous attempts to solve this usually required hybrid models that combined both Attention and SSM blocks, rather than relying on a pure Mamba architecture.
“Overall, the distilled Mamba model retains most of the original Pythia-1B Transformer performance, reaching a perplexity of 14.01 close to the teacher’s 13.86.”
— Attention to Mamba: A Recipe for Cross-Architecture Distillation
The Two-Stage Distillation Recipe
To solve this, researchers proposed a principled two-stage distillation approach. In the first stage, knowledge is distilled from a traditional Transformer into a linearized version of Attention. This step utilizes an adaptation of the 'kernel trick' to simplify the attention mechanism into a form more compatible with SSM structures.
In the second stage, this linearized Attention model is then distilled into an adapted Mamba model that contains no Attention blocks. By using this intermediate step, the researchers were able to equip Mamba with a 'principled initialization' that allows it to recover the performance lost during direct distillation.
Performance and Limitations
The results show that the distilled Mamba model retains the majority of the Pythia-1B Transformer's performance. While the perplexity scores are very close, the researchers noted that some performance gaps appear in specific tasks that rely heavily on in-context recall.
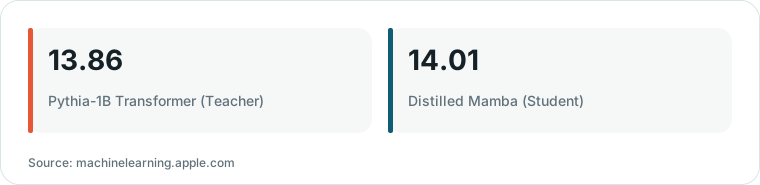
Chart drawn by HN Digest from figures reported by machinelearning.apple.com; values are shown as written in the source.
The study included thorough ablations at a 1B scale with 10B tokens to test different sequence mixer architectures. They also conducted scaling analysis on model sizes and sensitivity analyses on how tokens are allocated between the two distillation stages to optimize the process.