Chimera Vocal Synth moves away from traditional sample-based synthesis by using physical modeling to simulate the biological mechanics of the human vocal tract. Instead of playing back recorded snippets of speech or song, the engine calculates the physics of air moving through a simulated airway, including the lungs, vocal folds, lips, and nose, to generate sound in real-time.
Physical Modeling vs. Sample Synthesis
Most modern vocal synthesizers rely on concatenating pre-recorded audio samples or using neural networks to predict waveforms. Chimera takes a different approach by modeling the physical properties of the vocal apparatus. Every sound produced is a result of a simulated airway, which includes components like the syrinx (for birds), vocal folds, and a branched vocal tract.
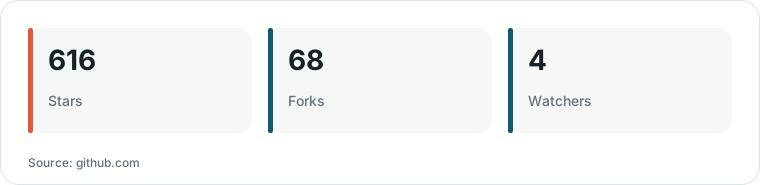
Chart drawn by HN Digest from figures reported by github.com; values are shown as written in the source.
By simulating these physical structures, the software can blend different body types—such as male, female, and child—continuously. The interface animates these states in real-time, displaying variables such as airway pressure, airflow, and the specific spectra of the vocal folds.
“A physical-modeling voice synthesizer in the browser. Every sound comes from a simulated airway (lungs, vocal folds or syrinx, a branched vocal tract, lips, nose), not from samples.”
— GitHub - jamesondh/chimera-vocal-synth: the ultimate vocal synthesizer - sing, speak, beatbox, and more
Technical Architecture and Interaction
The core engine is built in Rust to ensure real-time determinism and performance. It is compiled to WebAssembly (Wasm) to run within a browser's AudioWorklet, allowing the complex physics calculations to occur with low latency. The same codebase is used for native testing and a command-line interface (CLI) for offline rendering and diagnostics.
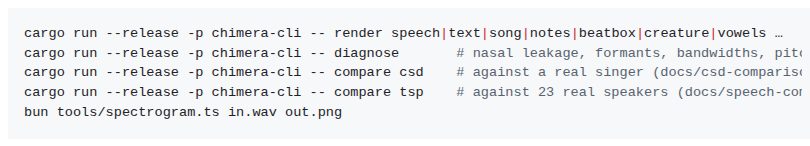
This image illustrates the Rust-based codebase mentioned in the technical architecture section.
The project offers several distinct modes for generating audio. Users can 'Speak' by inputting English text or IPA, which the system converts into gestures and prosody. For 'Singing,' the tool provides a piano roll where consonants are automatically timed to land before the beat. A 'Beatbox' mode uses pads and a step sequencer to map drum sounds to specific articulatory gestures.
Applications and Visual Feedback
A key feature of Chimera is its visual feedback, which provides a live cutaway of the head. This allows users to see the physical positions of the tongue, lips, and jaw as they manipulate the sound. This visual mapping of articulatory gestures could be useful for applications such as language learning or voice affirmation training, where understanding the physical mechanics of speech is beneficial.
The system also explores non-human vocalizations through its 'Bestiary' mode. By adjusting the parameters of the simulated airway, the software can replicate the sounds of various animals, including an alligator or an elephant. While the project provides a high degree of expressive control, the source material does not specify the exact latency overhead of the WebAssembly implementation compared to the native Rust execution.
What Hacker News readers are saying
- Alternative: One commenter shared their experience using the tool to produce specific overtone sounds, noting that they were able to simulate anatomical positions to achieve certain results. comment ↗
- Alternative: Another user suggested that the technology could be practically applied to voice affirmation training for transgender individuals or for assisting with language learning. comment ↗
- Skeptical: One commenter reported technical difficulties, stating that the engine failed to load properly on a mobile device and only produced noise. comment ↗
Summarized opinions from the Hacker News thread, not verified facts. Read the full discussion ↗