A two-person research lab has released a text-to-image model called Pyramid-JiT (P-JiT), designed as a proof-of-concept for more efficient generative video models. The project's primary goal was to address the high computational costs of video generation, which are often driven by the quadratic complexity of attention mechanisms. By moving away from traditional Variational Autoencoders (VAEs) to compress images into a latent space, the researchers aimed to bypass the empirical ceilings of VAE compression and learn more efficiently in a pixel-space environment.
The P-JiT architecture achieves this by using a 32x32 token reduction, which represents a 4x reduction in the attention context window compared to standard models like FLUX-2. To accelerate convergence, the team implemented a 'curriculum' over the noise schedule: the model first trains on high-noise samples to learn basic structures before widening the distribution to capture fine-grained details. The training regime involved 660 million samples, utilizing a 2-billion-parameter Diffusion Transformer (DiT) and a frozen Qwen3.5-4B text encoder. The total compute cost for pretraining and post-training on H100 GPUs was approximately $21,038.
While the model demonstrates high-quality results for portraits and landscapes, its smaller size introduces specific trade-offs in complex scene generation. The researchers noted that the model struggles with multi-person interactions, many entities (such as a pile of screwdrivers or a crowd of seagulls), and world knowledge. Additionally, because the model was not trained on rendered text, it cannot generate infographics or posters. These limitations are expected consequences of the 2B-parameter scale, which the team suggests could be mitigated by training larger models and applying further post-training techniques like Finite Difference Flow Optimization (FDFO).
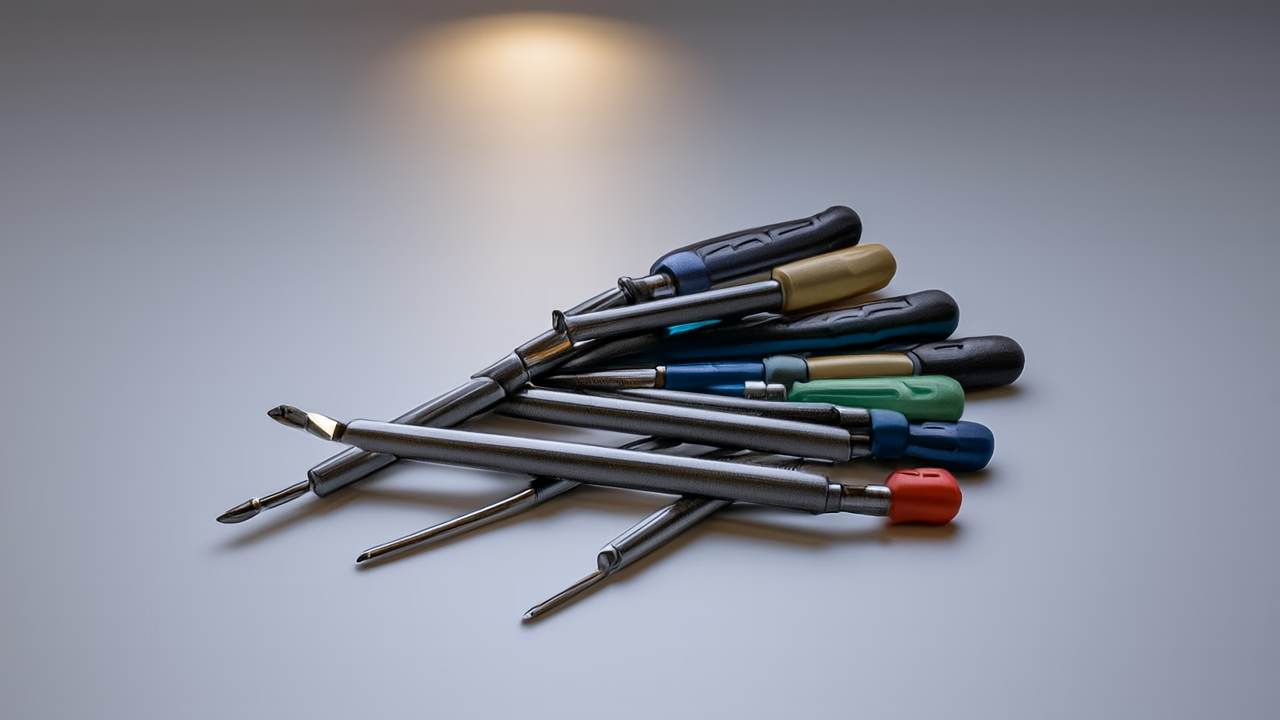
This image illustrates the model's difficulty with generating many distinct entities in a single scene.
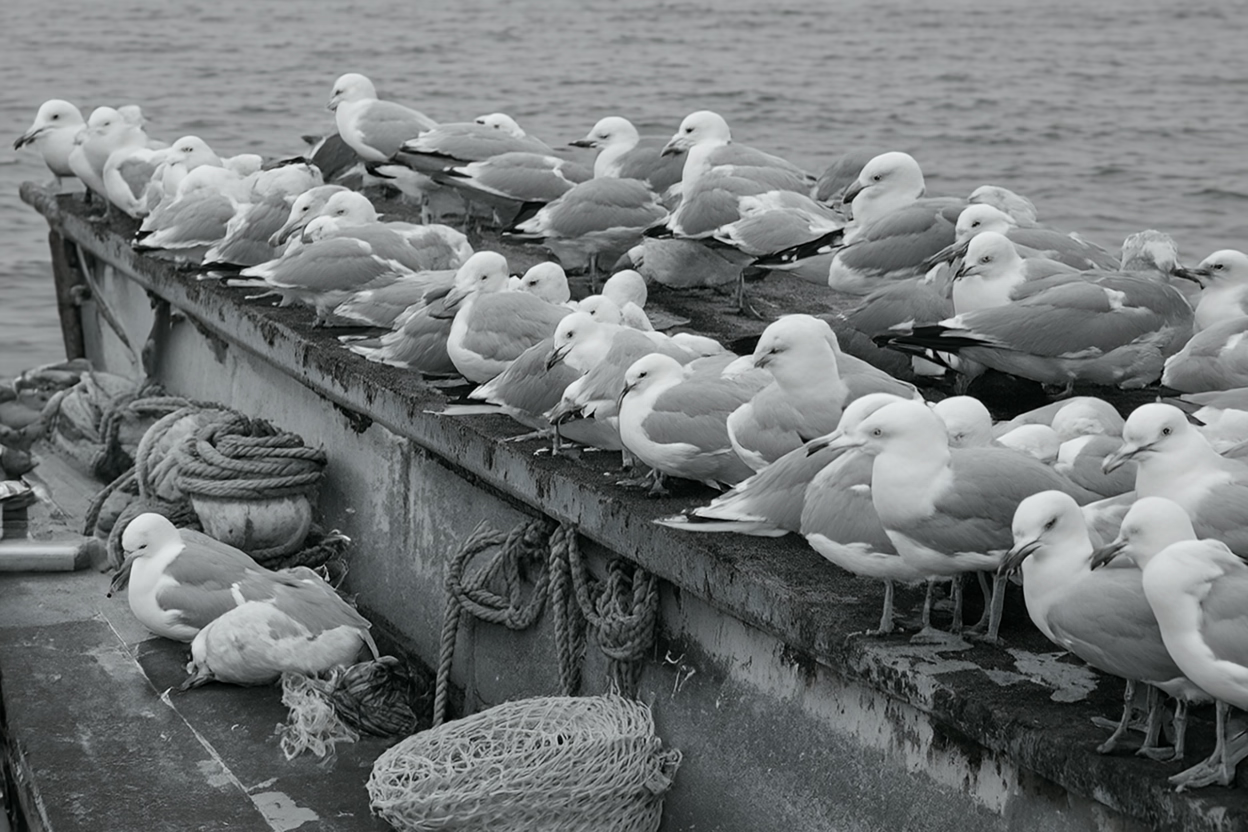
This visual demonstrates the specific limitation regarding crowds and multiple entities mentioned in the text.
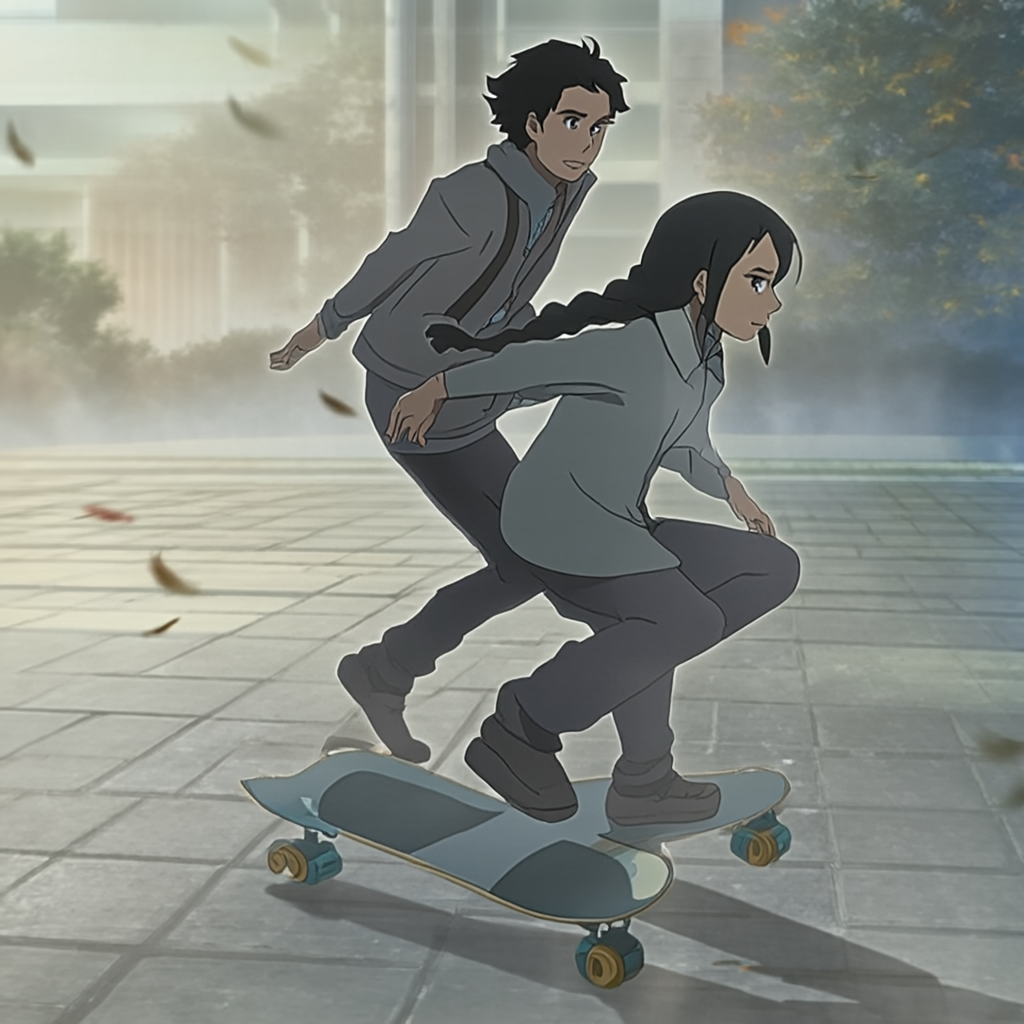
This image provides a concrete example of the model's struggle with multi-person interactions.