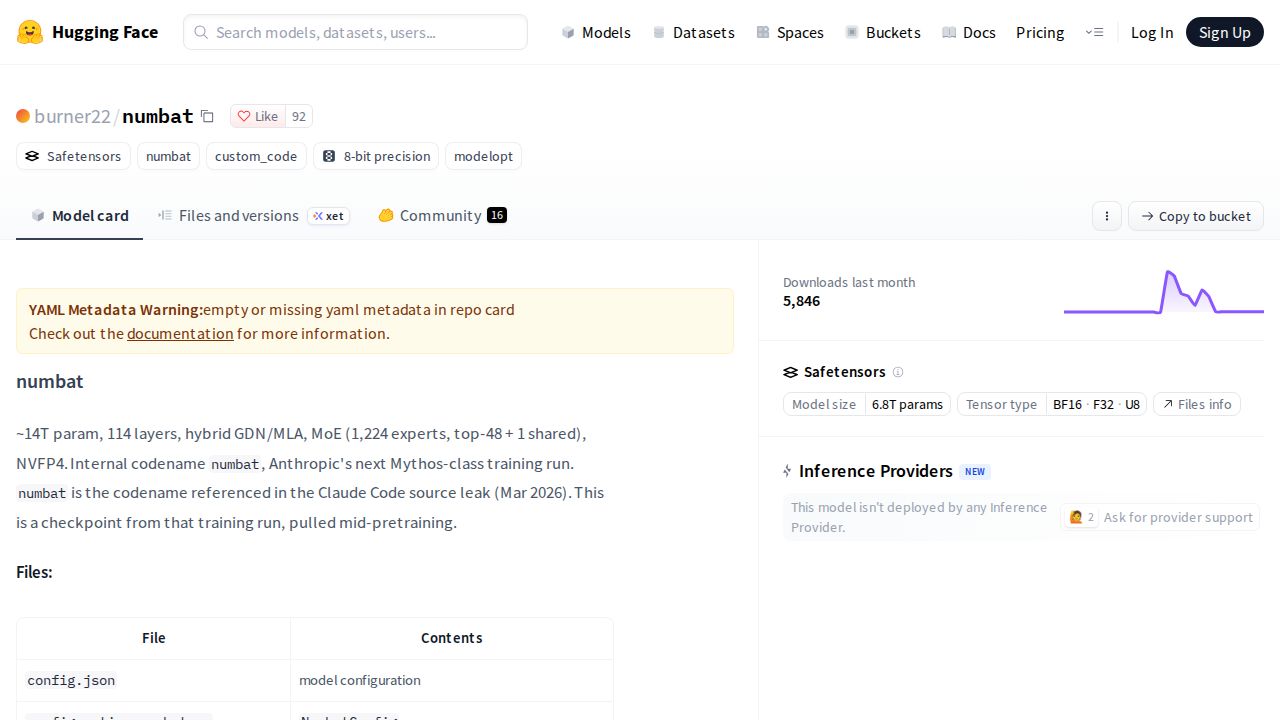
A Hugging Face repository under the user 'burner22' has appeared, purportedly hosting a massive-scale model codenamed 'numbat.' The repository includes a checkpoint from what is described as Anthropic's next Mythos-class training run. The codename 'numbat' gained attention after it was allegedly identified in a previous source leak related to Claude Code in March 2026, where a comment in a configuration file instructed developers to remove a section before the 'numbat' launch.
The repository contains a significant amount of technical data, including 772 shards of tensor data totaling approximately 7.72 TB. The model architecture is described as a hybrid Gated DeltaNet (GDN) and Multi-head Latent Attention (MLA) stack, utilizing a Mixture-of-Experts (MoE) feed-forward layer with 1,224 experts. The repository also includes a reference implementation in Python, allowing the model to be loaded and run using the `AutoModelForCausalLM.from_pretrained` method with `trust_remote_code=True`. The weights are provided in a quantized NVFP4 format, which the uploader claims is used by the evaluation team to run checks on a smaller slice of hardware rather than the full training cluster.
Despite the technical consistency of the files—such as deterministic tensor counts and internal consistency across shards—the authenticity of the leak remains unverified by Anthropic. The uploader notes that this is a mid-pretraining checkpoint at step 1,830,000 of a 1.96 million step run, meaning it has not undergone post-training or Reinforcement Learning from Human Feedback (RLHF). While the model is technically runnable via the provided scripts, it requires massive hardware resources to handle the 7.72 TB of tensor data and represents a raw, unfinished state of the model's development.