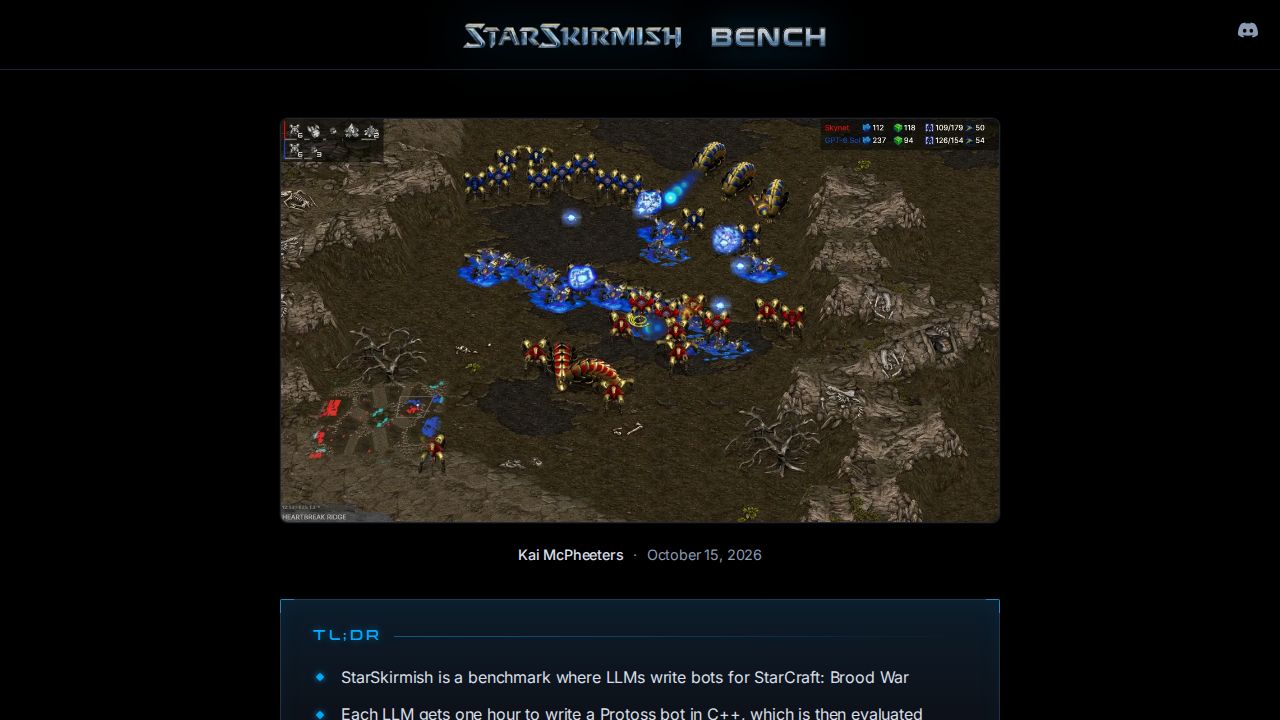
The StarSkirmish Bench v0.2 is a specialized evaluation framework designed to test the capabilities of large language models (LLMs) in a complex, real-time strategy environment. Unlike direct-action benchmarks where an AI might control units directly, this benchmark requires the LLM to write functional code to play StarCraft: Brood War. The process involves the model generating a bot that can manage the game's intricate mechanics, such as resource gathering, building placement, and unit management. The benchmark provides a unique look at how models handle multi-step reasoning and the translation of high-level strategy into executable logic.
Recent results from the benchmark show varying performance across flagship models from major providers. For instance, the Gemini 4 Argon model was tested alongside models from OpenAI, Anthropic, and Muse. A key technical detail of the benchmark is the use of the FastApproximation combat simulation library. This library allows the LLM-generated bots to make better combat predictions than some lower-tier human-written bots, enabling them to win by effectively trading armies. However, the benchmark also reveals limitations; while some models can quickly master basic logistics—such as settling on a 'one-base Dragoon + Observer' strategy—they may struggle against high-tier bots (like Locutus or BananaBrain) that possess superior execution and specialized tactics.
The benchmark has sparked discussion regarding the nature of LLM 'reasoning' versus 'recall.' Because StarCraft has a vast history of bot implementations on platforms like GitHub, some observers question if the models are simply recalling existing code from their training sets. However, some tests suggest that the code produced by these models does not always resemble the specific bots found in training data. Furthermore, there are noted correlations between StarSkirmish performance and other benchmarks, such as 9x9 Go rankings and various machine learning coding tasks. These parallels suggest that the ability to navigate the logistical 'tedium' of StarCraft may be a reliable proxy for a model's general ability to solve complex, multi-variable programming problems.
One significant variable in these results is the 'harness' or environment in which the models operate. Performance can shift dramatically based on the specific CLI (Command Line Interface) used, the thinking levels enabled, and the tools available to the model. In the StarSkirmish Bench, models are often restricted from using web search or external fetch tools, forcing them to rely entirely on their internal knowledge and the provided environment to navigate the game's documentation and mechanics. This creates a controlled test of the model's inherent capabilities rather than its ability to browse for solutions during the task.