PS5LM is an open-source project designed to leverage the PlayStation 5's hardware for local AI inference. By utilizing the console's RDNA 2 GPU via the Vulkan backend of llama.cpp, the software allows users to load and run GGUF (GPT-Generated Unified Format) models—a common format for quantized large language models—directly on the device. The system utilizes approximately 11.4 GB of the console's shared memory for the model and its context, supporting various architectures and quantization methods supported by the llama.cpp framework.
The project functions as a private model server that serves requests to other devices on a local network, such as laptops, phones, or coding tools. It provides compatibility with standard APIs, including OpenAI's /v1/chat/completions and Anthropic's /v1/messages, allowing it to interface with existing software like Claude Code. Beyond standard chat, PS5LM supports 'decision models'—models designed to output typed decisions, scores, and yes-or-no answers in a single forward pass rather than generating long strings of text. The console's interface displays real-time telemetry, including temperature, power consumption, and GPU/CPU load, while streaming requests and replies across the TV screen.
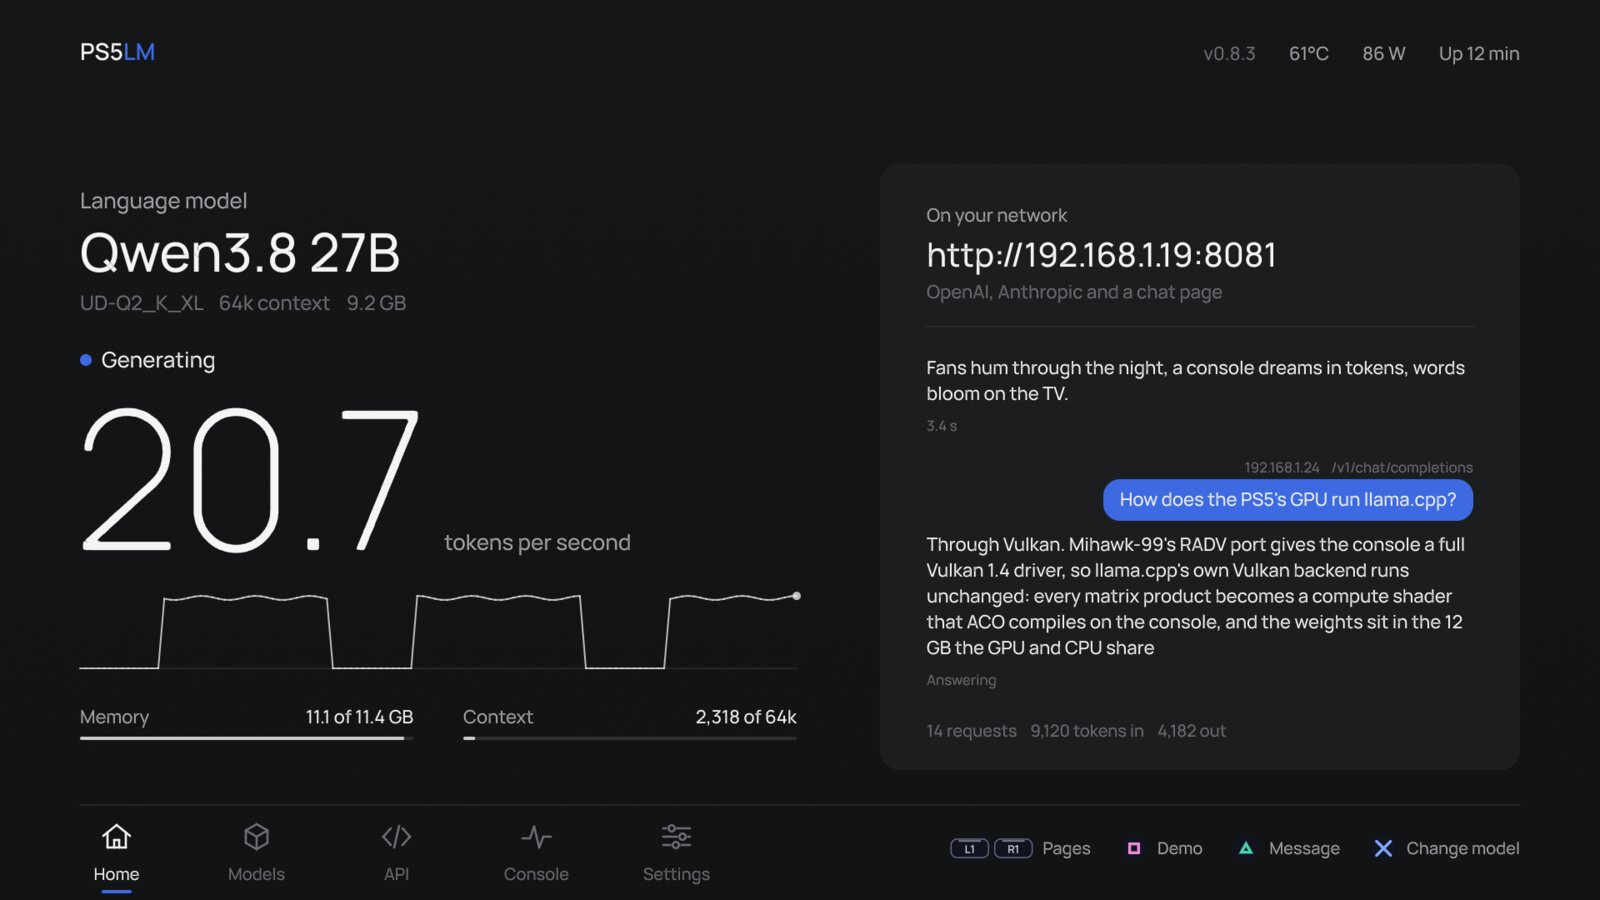
The project provides a user interface that displays real-time telemetry and streaming requests across the TV screen.
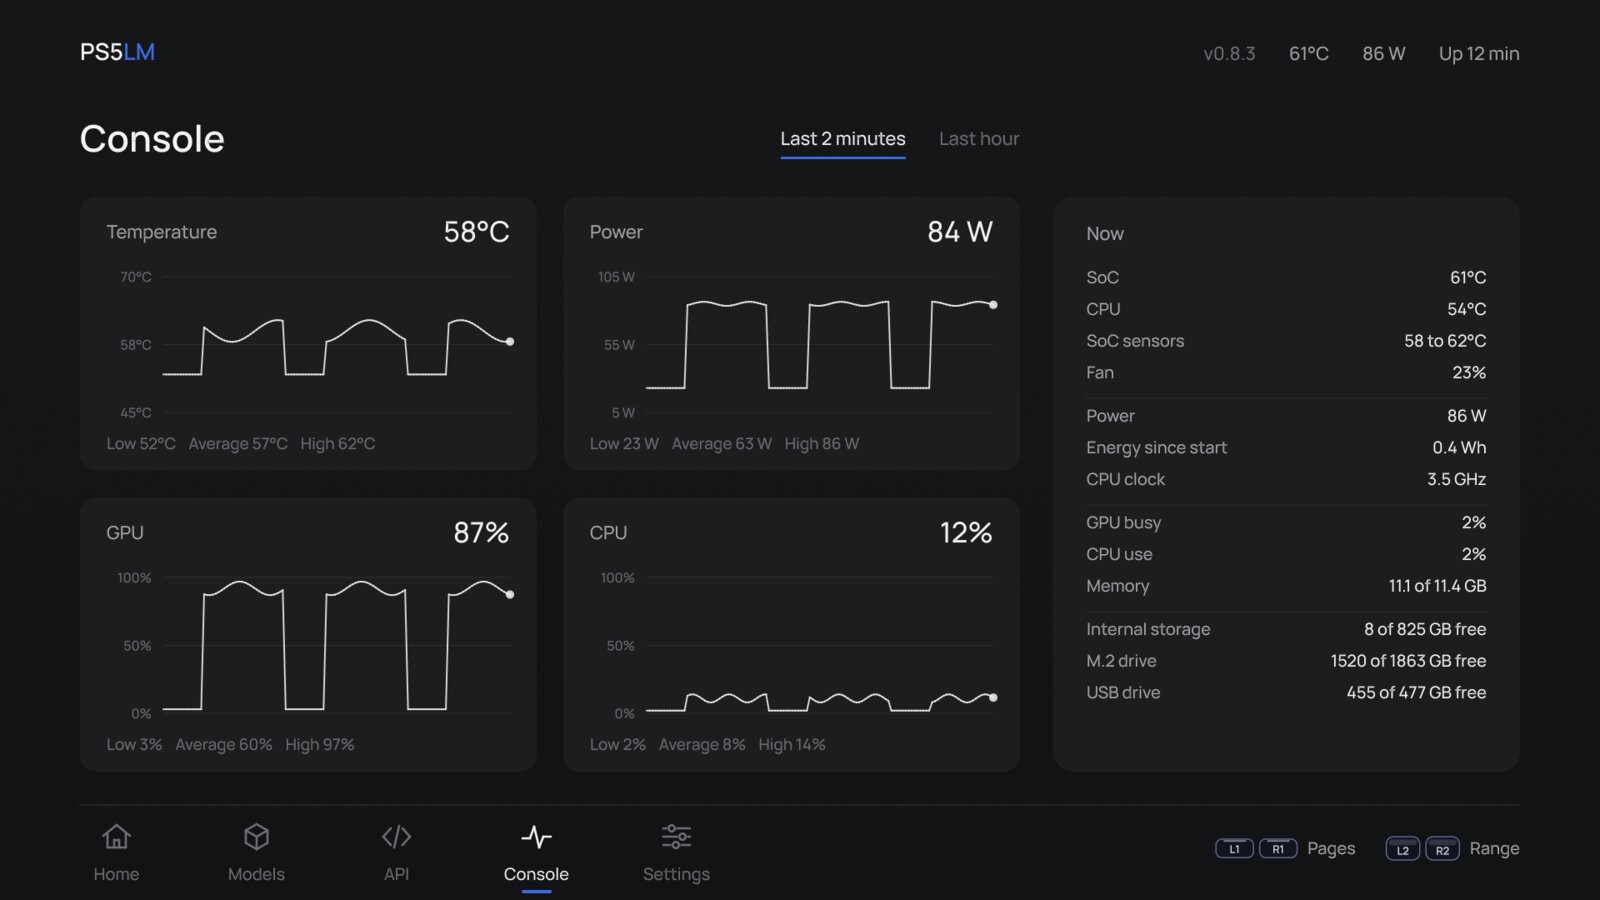
The console's interface displays real-time telemetry, including temperature, power consumption, and GPU/CPU load, while streaming requests and replies across the TV screen.
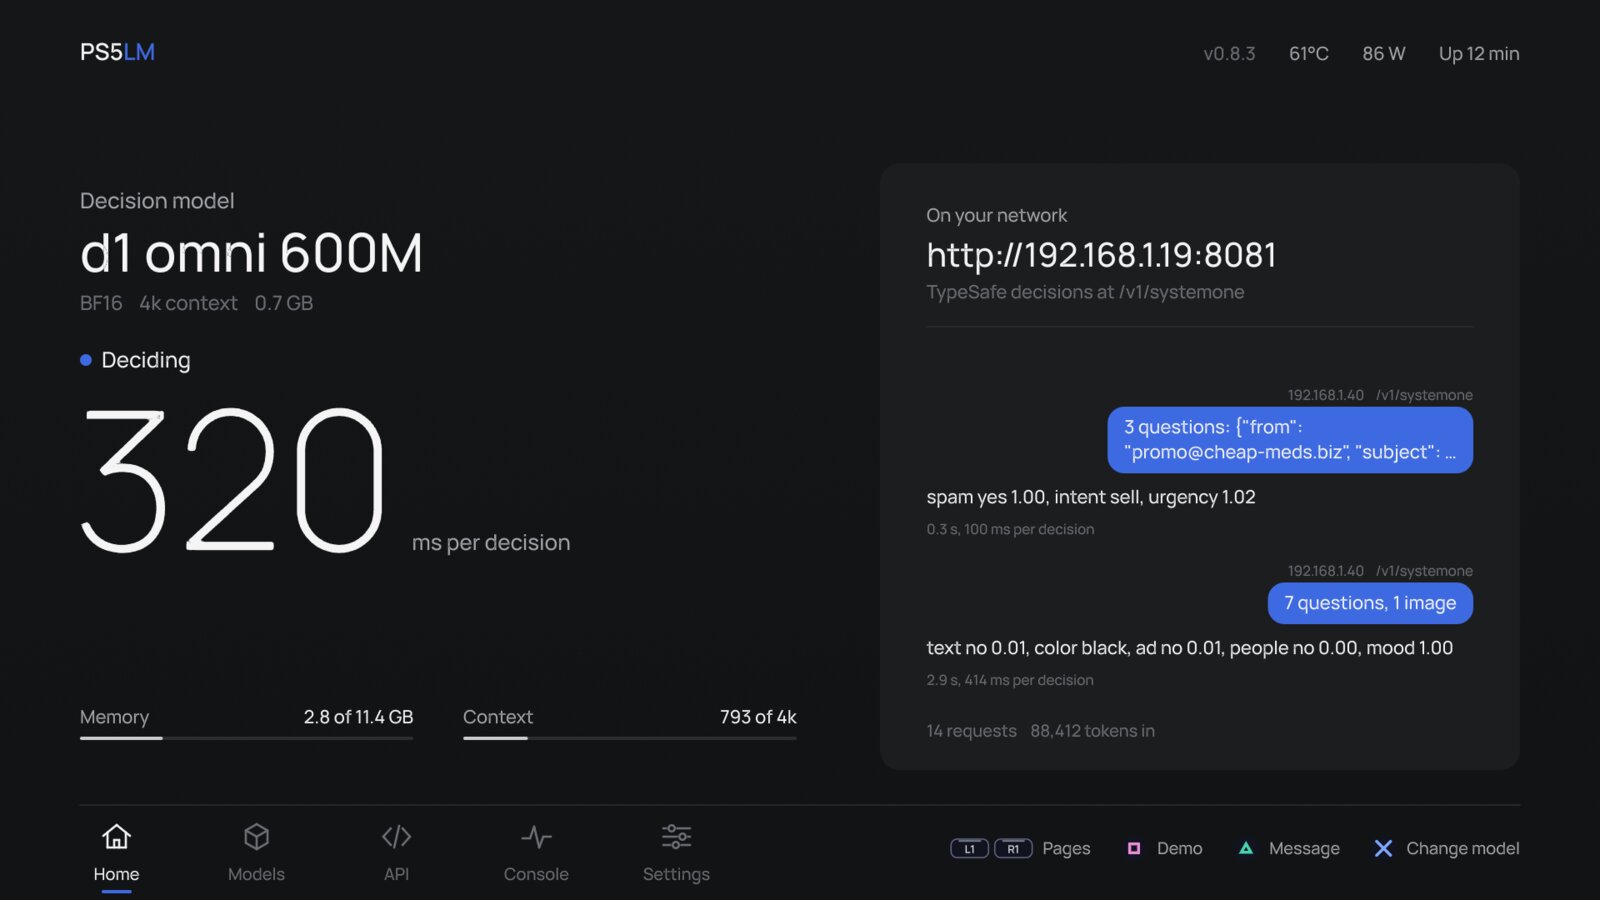
Beyond standard chat, PS5LM supports 'decision models'—models designed to output typed decisions, scores, and yes-or-no answers in a single forward pass rather than generating long strings of text.
While the project offers a way to run models like Qwen 3.5 and Qwen 3.8 natively, it carries specific hardware and software requirements. Users must have a jailbroken PS5 running firmware between versions 7.00 and 13.60, along with several specific payloads (such as etaHEN, ShadowMountPlus, and elfldr) to enable homebrew support and file system access. Performance varies significantly based on the model size; for example, a Qwen 3.5 9B model can achieve roughly 55 tokens per second on a PS5 Slim, while a larger Qwen 3.8 27B model (at a 2-bit quantization) can reach about 20 tokens per second with a 64k context window. Because it runs locally, the system requires no cloud connection or external accounts, providing a private alternative for home AI hosting.