For developers building applications powered by Large Language Models (LLMs), the primary interface is often a simple frontend or a paid subscription. However, this abstraction can obscure the underlying mechanics of how data travels from a user's prompt to a provider's inference engine. A self-hosted LLM proxy acts as a transparent middleware layer, sitting between the local client (such as a coding assistant or a custom application) and the upstream cloud provider (e.g., OpenAI, Anthropic, or Google). By owning this infrastructure, developers can move beyond basic usage statistics to gain deep, time-series insights into token consumption and model performance.
One of the primary technical advantages of a self-hosted proxy is the ability to manage complex, multi-provider environments from a single endpoint. This allows for rapid pivoting between different models and providers without reconfiguring the entire application stack. Furthermore, these proxies enable the use of virtual API keys, which prevent the leakage of primary credentials across various agents and development harnesses. Beyond configuration, self-hosted proxies provide critical security features, such as automated redaction of secrets (like AWS keys or GitHub tokens) and 'anti-poisoning' stacks that detect prompt injection attempts before they reach the model. This ensures that sensitive information is stripped from the payload, reducing the risk of data exfiltration.
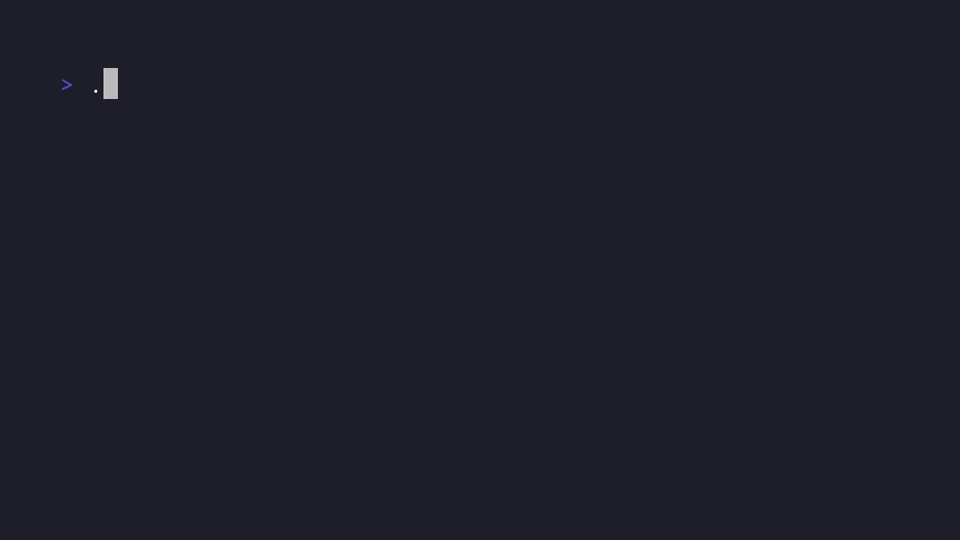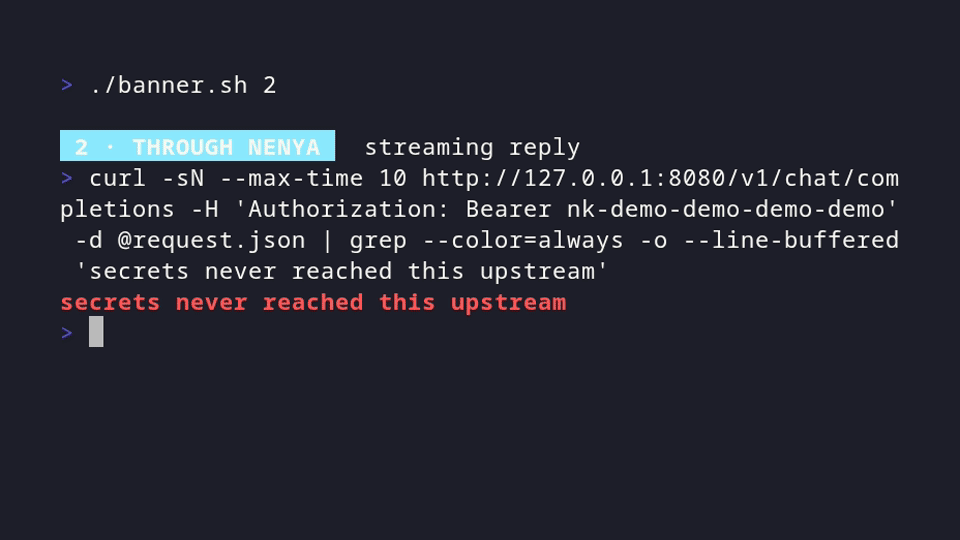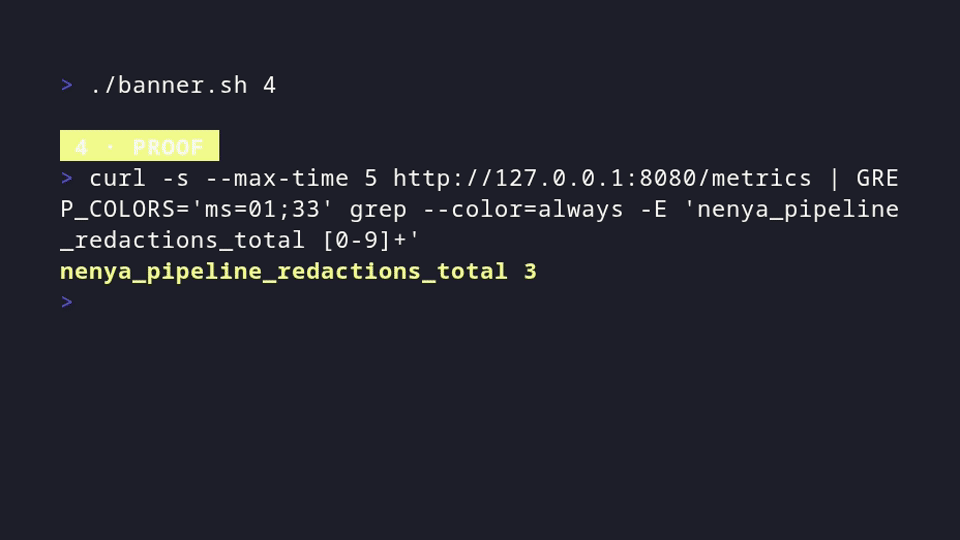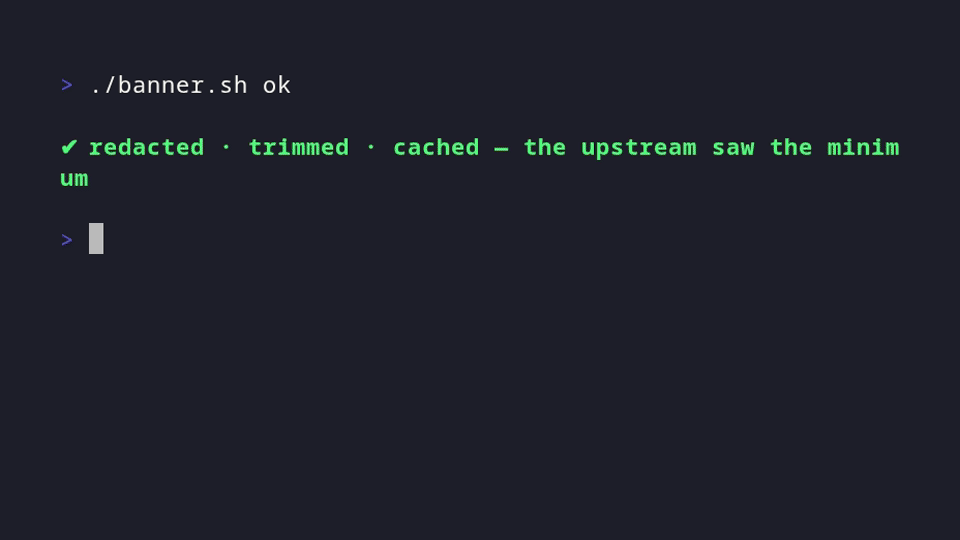
This visual illustrates the automated redaction of secrets and anti-poisoning stacks mentioned in the text.
Despite these benefits, the decision to run a proxy involves trade-offs regarding complexity and cost. While a proxy provides superior visibility into 'cache misses' and specific model behaviors, it requires maintaining additional infrastructure. For users on flat-rate subscriptions rather than pay-per-token API models, the value proposition shifts; some argue that local file collection is sufficient for monitoring, while others maintain that a proxy is essential for capturing the full scope of agentic behavior across an organization. Ultimately, a self-hosted proxy transforms the LLM interaction from a 'black box' into an instrumented data path, allowing engineers to pinpoint exactly why a specific request failed or succeeded in real-time.