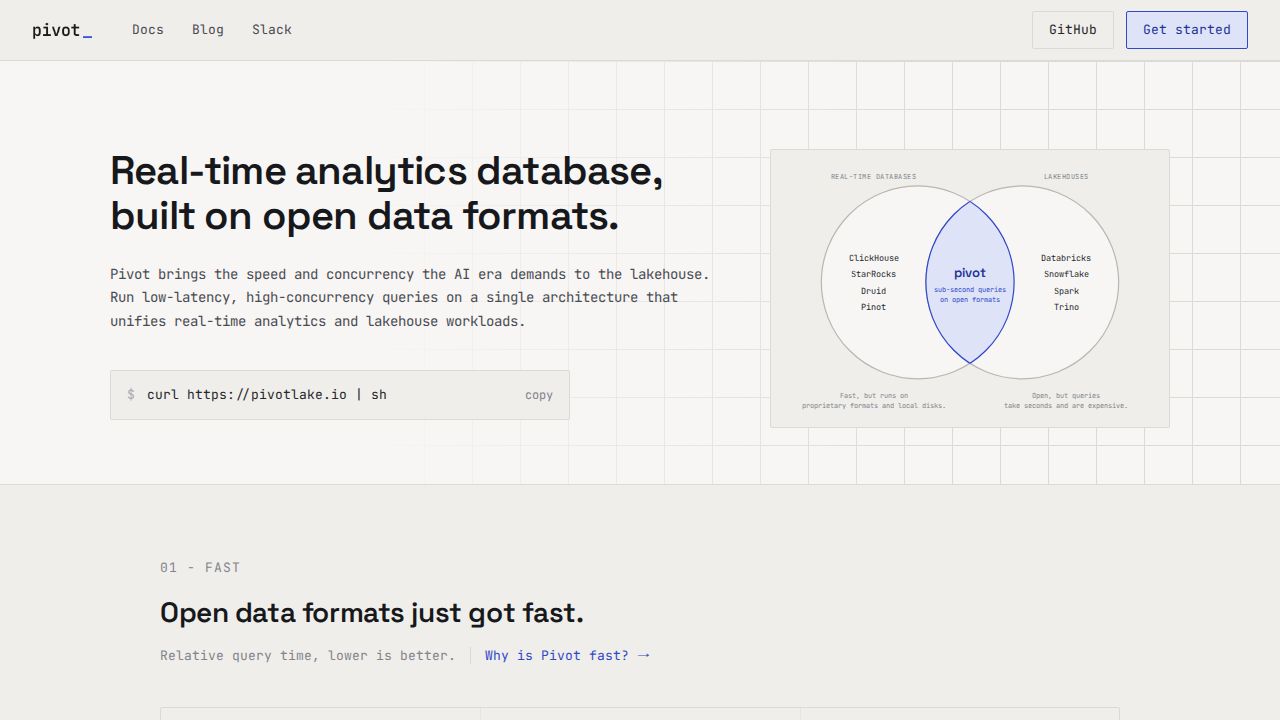
Pivot is an open‑source analytics database that lets users run low‑latency, high‑concurrency SQL queries directly on open data formats such as Apache Iceberg and Delta Lake without first copying the data into a proprietary engine. It speaks the Postgres protocol on port 5432, so existing SQL clients, business‑intelligence tools, and AI agents can connect with psql or any Postgres‑compatible driver and query data that remains in object storage.
Performance measurements included in the project’s documentation show Pivot outpacing established analytical databases. In the ClickBench suite of 43 queries, Pivot (Parquet) recorded a relative time of 1.09×, while ClickHouse (native) was 2.17× and DuckDB (native) 4.17×—meaning Pivot runs roughly twice as fast as ClickHouse and nearly four times faster than DuckDB. On the TPC‑H SF1000 benchmark, Pivot (Parquet) set the baseline at 1.00×, with DuckDB (Parquet) at 2.16×, ClickHouse (native) at 3.10× and Spark at 53.73×. The project attributes these gains to a Rust‑based engine that uses Arrow for in‑memory data, a thread‑per‑core execution model, a custom memory allocator, and tuned JOIN and GROUP BY algorithms that maximize modern CPU memory bandwidth.
Beyond speed, Pivot emphasizes operational flexibility and openness. Because it treats object storage as the sole source of truth and keeps only transient state in memory, instances can be scaled up, down, or to zero almost instantly, enabling burst‑y workloads or cost‑saving autoscaling. Users may run Pivot as a shared server for concurrent access or launch it locally from a terminal for ad‑hoc queries, both paths accessing the same tables in object storage. The benchmark harness and queries are publicly available in the repository, and the reported numbers were obtained on AWS c8gd.metal‑48xl instances, so results may differ on other hardware or workloads.