In September 2026, the team behind Wagtail CMS—a Python-based content management system—embarked on an experiment they called their 'open models only: back to school challenge.' The goal was deceptively simple: spend the whole of September coding with only one efficient open-model tier, specifically GLM 5.3 Flash. As the team explains, 'Setting a challenge to spend the whole of September on only one efficient open model felt like a great idea at the time.'
The model chosen was GLM 5.3 Flash, a tier of efficient open-source AI models. According to the Wagtail blog, GLM 5.3 Flash features a 1M context window, enabling extended coding tasks and complex reasoning. It also offers vision support, meaning it can work with screenshots or visual QA. The model is available across a wide range of providers, benefiting from healthy competition. These technical strengths made it well-suited to the challenge the team set for itself.
What went well during the month? The team successfully spent the first half of September using only GLM 5.3 Flash. That model's usage stayed well within budget: approximately $68 in cost, about 4 kWh of energy use, and 365 grams of carbon emissions. To put this in perspective, the team notes this energy use is equivalent to driving an electric vehicle about 15 miles or boiling 10 gallons of water. GLM 5.3 Flash itself proved excellent for the tasks the team needed: building sites with Wagtail itself, UI tasks, AI research and development work, documentation writing, and code evaluation. The model's versatility made it 'really polyvalent' for their workflow.
However, the second half of the month didn't go as planned. About 1B tokens went to other models, bringing total token usage to 2B instead of the target 1B. About 35 kWh of energy use accumulated instead of the expected 10 kWh. The team identified several unexpected hurdles.
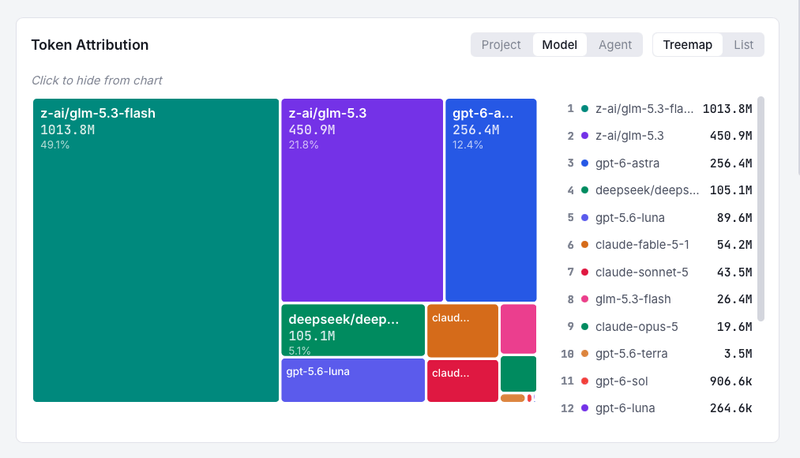
Visual representation of the experiment's key finding: only 50% of tokens went to the target model, with half going to other models
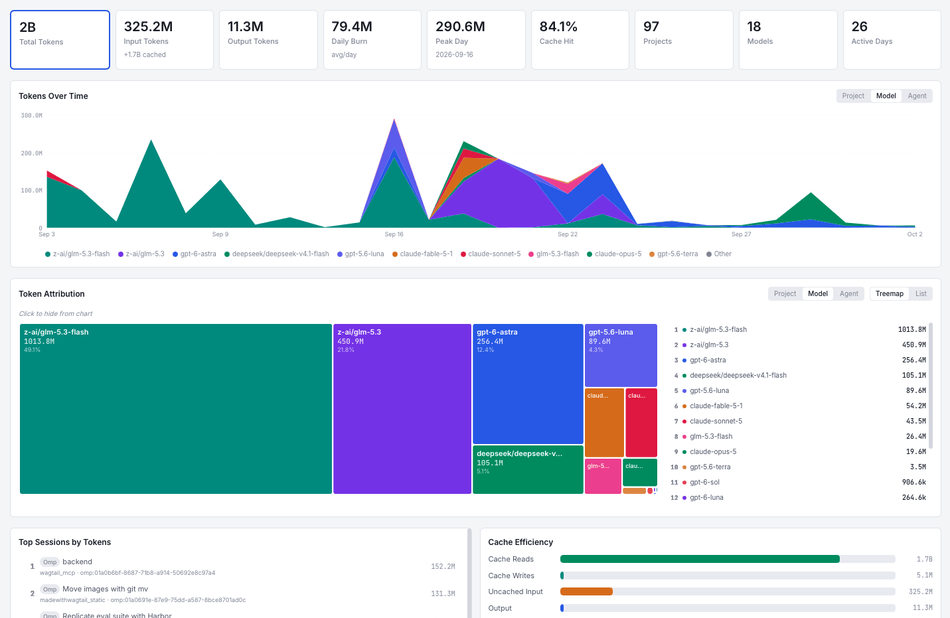
Screenshot showing the total token consumption that exceeded the 1 billion target, illustrating the scale of the overshoot
One significant issue was what the team calls 'the cost of vibe coding.' Their experimental Wagtail MCP server—a vibe-coded prototype—was using the 'wrong' model for the prototype purpose. They chose a model that resulted in spending 450M tokens / $150 / 5 kWh of energy use almost overnight. The team acknowledges this was a prototype mistake: 'We could have achieved similar results for most likely 5x less cost with not that much more effort.' The lesson: be careful with model selection and agentic patterns. They needed to budget for this and be more careful; they could have seen it coming, but now they do.
Another hurdle was infrastructure availability. The team had written extensively about comparing inference providers. Their choices work well most of the time, but these models are very popular, and they don't have the same capacity as the big labs who hoard all the GPUs. For their situation, with only open models confirmable as available in a European data center, performance degradation with GLM 5.3 Flash was likely because it's 'so high up the Pareto frontier of relevant models for our work.' When GLM 5.3 Flash underperformed, the team had to switch to other similar models: DeepSeek V4.1 Flash and Qwen 3.8 Flash. This switch was 'very simple to do, but nonetheless unexpected.'
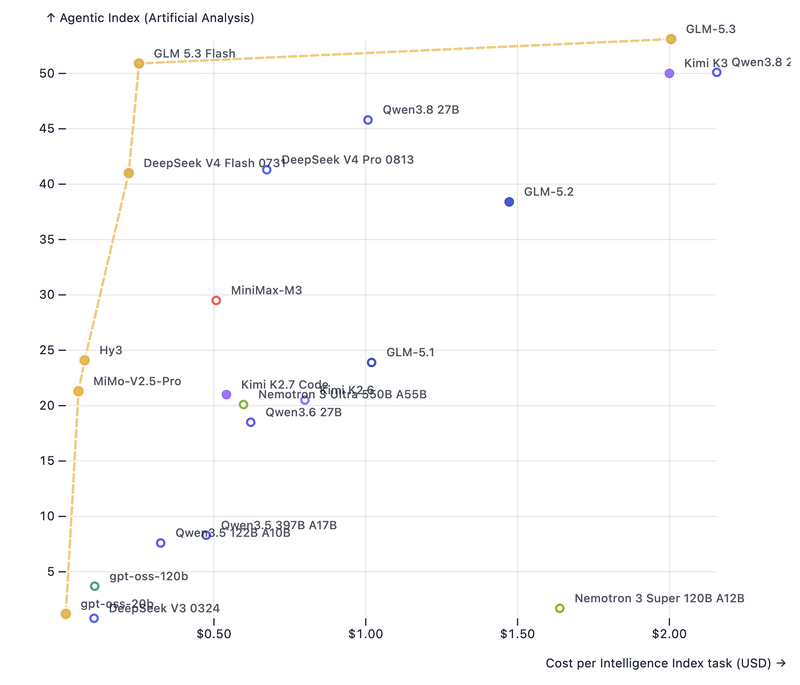
Graphical illustration of the model selection challenge discussed in the article, where high-performance models like GLM 5.3 Flash sit at the Pareto frontier
Beyond using one model for day-to-day engineering, the team felt essential to keep experimenting with a wide range of models, keeping up with what providers are releasing. This is particularly essential as they start benchmarking models' performance on Wagtail tasks, where they need data across a wide range of models. The team shares a sneak peek of their benchmark, noting it's 'much easier to guide people towards leaner options with this kind of concrete data.'
The team's takeaways and what to do next are straightforward. Technically, the challenge was a failure: only 50% usage on the target model, 1B out of 2B tokens. About 35 kWh of energy use instead of 10. But they learned a lot, which the team considers crucial for the current moment. Reflecting on this for October, here's what will make it work:
- Constant, local usage measurement and reporting. Looking not just at tokens but also energy use and spend, and ideally how well this leads to concrete positive outcomes. - Budgeting for experimentation, not just day-to-day tasks. Making more concerted decisions about which prototypes are worth building, and how. - Better prompt selection and multi-agent techniques. Orchestrator vs. scout vs. implementer vs. reviewer agents. Bounded goals. Not rocket science but certainly one more thing to learn. - Keep pushing for more efficient techniques and models. The Jev-style decision diffusion models look very promising if they can run so efficiently. Latest flagship models also look like a step in the right direction on that front.
For day-to-day developer work, the team concludes it's totally viable to focus on one or two flash-tier cheap models. A viable target is probably that the majority of AI inference work should be done with such efficient models, measured in cost or energy use rather than meaningless tokens. That's the goal for October—they encourage others to try it too, as they'll learn a lot in the process. They'll be at Wagtile Space 2026 in November to hear how it all pans out.
The experiment reflects a significant shift in AI development philosophy. The team argues that most AI inference work should move toward efficient models, measured in cost or energy rather than meaningless token counts. The experience suggests a new paradigm: not replacing powerful models like Claude Opus, but rather establishing efficient models as the workhorse for routine tasks, while reserving premium models for complex, novel challenges.
Looking forward, the Wagtail team plans to implement these lessons in October, aiming for more efficient AI usage patterns. They note that the current moment represents a critical opportunity to establish better practices before these efficient models become as competitive and in-demand as the frontier models they currently replace. The experiment concluded technically as a partial failure—only 50% usage on the target model—but serves as a crucial learning experience for the broader AI development community.